
AI Crawler Accessibility and Technical GEO: Implementation Guide
Definition, Risk And Controls
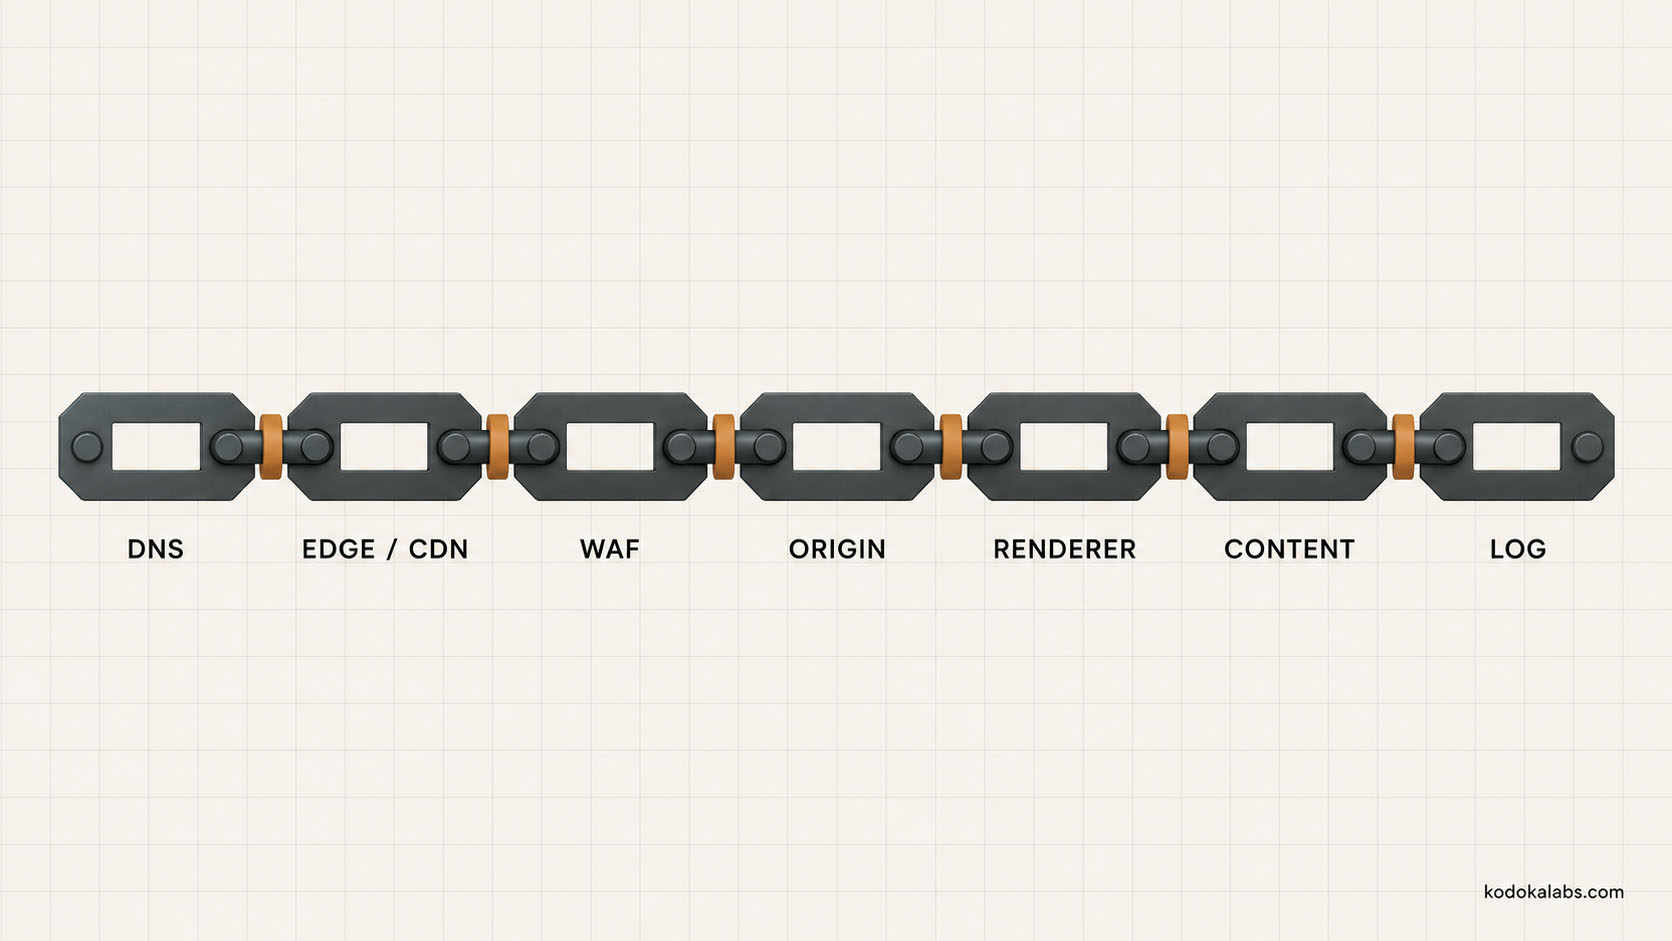
Technical GEO is the implementation discipline of making an organization’s intended public content genuinely reachable, fetchable, and interpretable by AI crawlers and retrieval systems, while preserving the security, privacy, intellectual-property, and operational controls the organization has deliberately chosen. The central technical insight this guide is built around: a correctly configured `robots.txt` file is necessary in some cases but is not, by itself, sufficient. Content delivery depends on a chain of independent systems, DNS, CDN, web application firewall (WAF) rules, authentication, server or client-side rendering, canonical tags, HTTP status codes, and sitemaps, and a failure at any point in that chain can silently block AI crawler access even when the robots configuration looks correct.
This guide is written for the people who actually implement and own these controls: technical SEO leads, web platform owners, developers, and security or CDN owners. Any recommendation involving WAF rules, IP allowlisting, or infrastructure-level access changes requires review and sign-off from the organization’s security owner before implementation; this guide provides the technical framework for that conversation, it does not substitute for it.
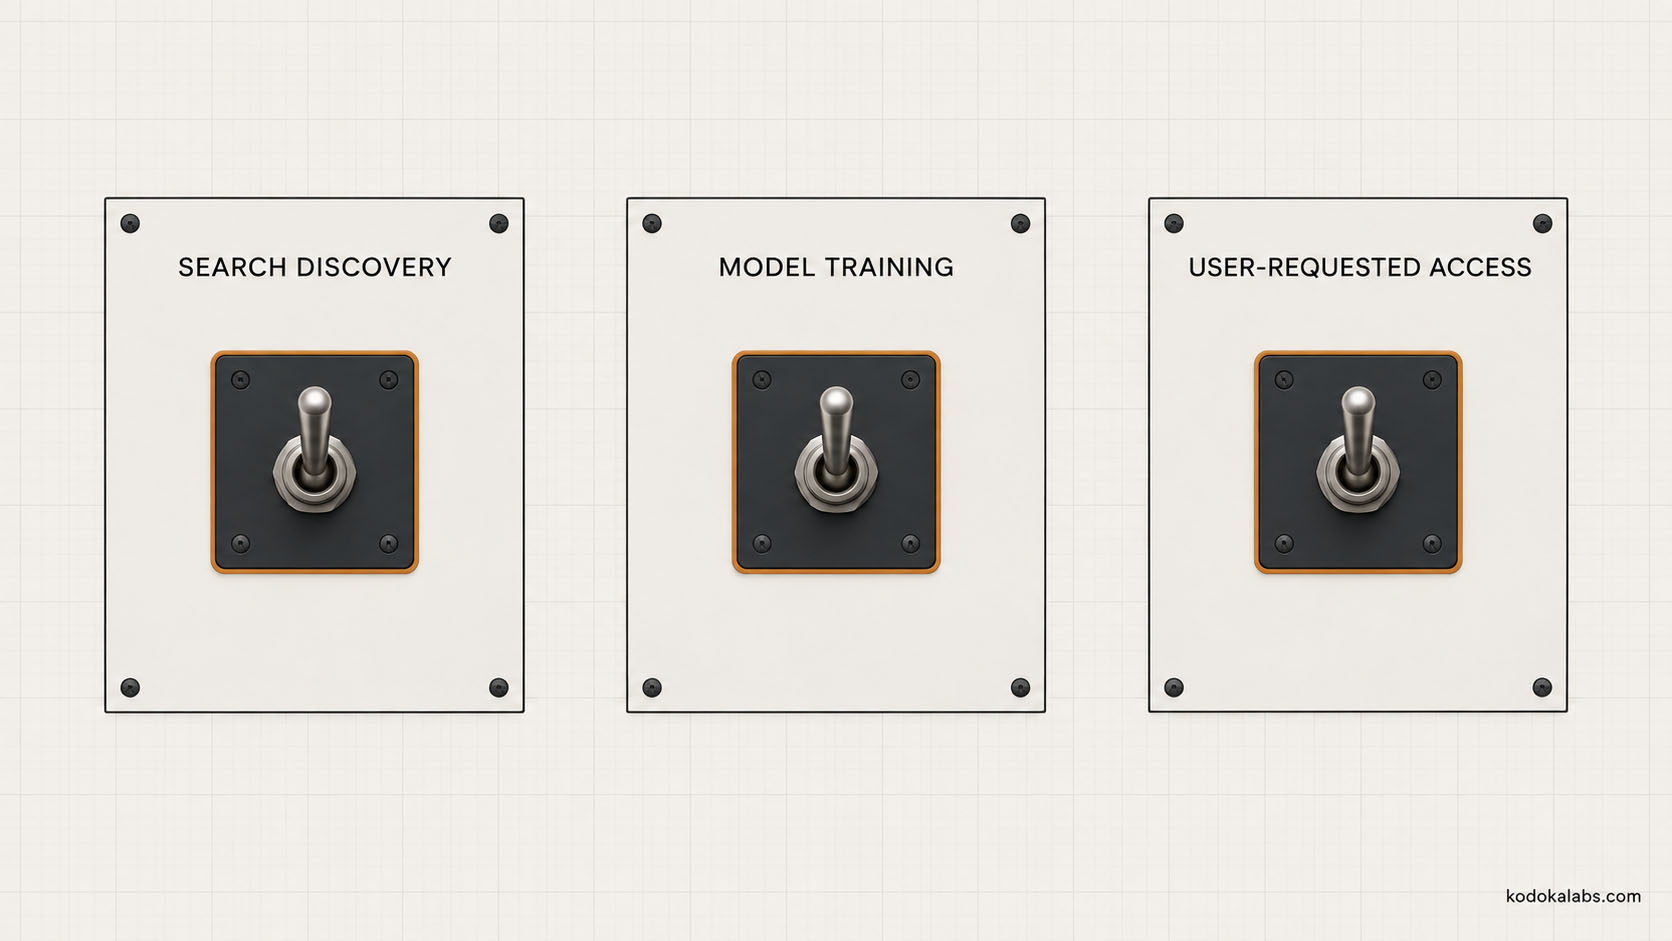
A foundational distinction this guide insists on throughout: search and discovery access, user-requested retrieval, and model-training data collection are separate purposes, often governed by separate crawler tokens from the same provider, and must not be treated as a single switch. Blocking a provider’s training-data crawler does not necessarily block that provider’s search-discovery crawler, and the reverse is also true; each needs its own deliberate
Crawler-purpose taxonomy
Understanding AI crawler access starts with understanding that a single AI company frequently operates multiple, separately documented crawlers or user-agent tokens for different purposes, and conflating them is one of the most common and consequential technical GEO mistakes.
OpenAI documents this separation explicitly: OAI-SearchBot is used to discover and retrieve content that ChatGPT can search and potentially cite in search-style responses, while GPTBot is used for model training and can be controlled independently of search discovery (OpenAI publisher and developer FAQ, reviewed 2026-09-14). A separate ChatGPT-User token exists for real-time, user-triggered fetches, such as when a user asks ChatGPT to retrieve or browse a specific page directly, distinct from both of the above; verify current documentation for this token’s exact behavior before relying on it, since OpenAI’s own materials note it evolves as product features change.
Perplexity documents a comparable purpose separation: an indexing crawler used to build its search index ahead of time, and a separate real-time user-fetch behavior triggered when a specific query requires live retrieval, each with its own published user-agent string and documented IP ranges for verification (Perplexity crawler documentation, reviewed 2026-09-14).
Google’s documentation describes Google-Extended as a control token, not a separate requesting user agent with its own crawl behavior; it allows a site to control whether content already reached through Googlebot’s normal crawling is eligible for use in Google’s AI training and certain generative features, and Google is explicit that it does not control eligibility for Google Search inclusion itself (Google crawler documentation, reviewed 2026-09-14). Googlebot and Bingbot remain the primary, long-documented crawlers for each engine’s core search index, on which AI features described elsewhere in this pillar substantially depend.
| Provider | Agent or token | Disclosed purpose | Distinct from |
|---|---|---|---|
| OpenAI | OAI-SearchBot |
Search discovery and retrieval for ChatGPT search-style responses | GPTBot (training), ChatGPT-User (user-triggered fetch) |
| OpenAI | GPTBot |
Model training data collection | OAI-SearchBot, ChatGPT-User |
| OpenAI | ChatGPT-User |
Real-time fetch triggered by a specific user request | OAI-SearchBot, GPTBot (verify current documentation before relying on exact behavior) |
| Perplexity | Indexing crawler (see current Perplexity documentation for exact token name) | Building Perplexity's search index | Perplexity's separate real-time user-fetch behavior |
| Perplexity | Real-time user-fetch | Live retrieval triggered by a specific query | Perplexity's indexing crawler |
Googlebot |
Core Search crawling and indexing | Google-Extended (a control token, not a separate crawler) |
|
Google-Extended |
Controls eligibility for Gemini and certain AI-feature training/grounding use of already-crawled content | Does not control Google Search inclusion itself | |
| Microsoft | Bingbot |
Core Bing Search crawling and indexing, underlying Copilot's web grounding | N/A |
Robots And Page-Level Controls
The Robots Exclusion Protocol, standardized in IETF RFC 9309, is a crawler-control convention: it tells a well-behaved crawler what it is asked not to fetch. It is explicitly not an access-authorization mechanism; it relies entirely on the requesting crawler choosing to honor it, and it provides no actual security barrier against a crawler, or any other automated client, that chooses not to comply. This distinction matters directly for how an organization should think about `robots.txt`: it expresses policy to cooperative, identifiable crawlers, it does not enforce access control.
At the page level, `robots.txt` directives, meta robots tags, and the `X-Robots-Tag` HTTP header each provide different granularity: `robots.txt` operates at the path or site level, while meta robots tags and `X-Robots-Tag` can apply directive-level control (such as `noindex` or `nosnippet`) to an individual page or a specific HTTP response. Where an organization wants a page crawled but not used in certain snippet-style features, `nosnippet` and comparable directives, documented per platform, are the correct tool, not a blanket robots block, which would prevent crawling entirely.
This guide deliberately does not publish a universal, copy-paste robots policy. The correct policy depends on an organization’s specific competitive posture, content strategy, and risk tolerance, decisions covered in the Policy decisions and rollback section below, and must be made deliberately rather than adopted as a generic template.
Infrastructure Access
Beyond `robots.txt`, several infrastructure layers can independently block or degrade AI crawler access regardless of robots configuration. A CDN or WAF may apply bot-management rules that block or challenge automated clients, including legitimate, well-behaved crawlers, unless those crawlers are explicitly allowlisted; this is frequently the actual cause of an AI platform failing to access content even when the site owner believes robots rules permit it. Authentication or consent-layer requirements placed in front of otherwise-public content will block any crawler that cannot pass through them, AI crawlers included.
Allowlisting a crawler at the WAF or CDN level should never rely on trusting the User-Agent string alone, since that string can be trivially spoofed by any client. Verify crawler identity through the provider’s own published verification method, typically reverse DNS lookup confirming the requesting IP resolves to the provider’s documented domain, cross-checked against the provider’s published IP ranges where available. Any change to WAF or CDN allowlisting rules is an infrastructure and security decision, requiring the organization’s security owner’s review and sign-off before implementation, with monitoring in place afterward and a documented rollback path if the change has unintended effects.
Rendering And Content Delivery
Whether content is served through server-side rendering, static generation, or client-side JavaScript rendering has a direct effect on AI crawler accessibility, since not every crawler executes JavaScript reliably or at all. Content that depends entirely on client-side rendering to become visible is at higher risk of being fetched as an effectively empty or incomplete page by a crawler that does not execute the relevant scripts. Server-side or pre-rendered delivery of the core content, with JavaScript enhancing rather than solely producing the essential text, is the more reliably accessible pattern across a wider range of crawlers.
Canonical tags need to resolve correctly and consistently, since a crawler encountering conflicting or broken canonical signals may treat the wrong version of a page as authoritative, or discount the page’s signals entirely. Sitemaps should accurately reflect the current, intended set of public URLs, since an out-of-date sitemap can either miss new content or continue referencing removed content, both of which create noise for any crawler relying on it.
Audit And Acceptance Test
| Check | What to verify |
|---|---|
| DNS | The domain resolves correctly and consistently for the crawler's request path |
| TLS | A valid, current TLS certificate is presented; the crawler can complete the handshake |
| HTTP status | The page returns a genuine 200 OK for the crawler's request, not a soft error, unexpected redirect, or block page |
| Robots | robots.txt, meta robots, and X-Robots-Tag directives are checked and confirmed to permit the intended access |
| Firewall or WAF | The specific, IP-verified crawler is not blocked or challenged by bot-management rules |
| Rendering | The content a crawler actually receives, tested via a crawler-equivalent fetch, matches the fully rendered page a human sees |
| Visible text | The key facts and definitions the organization intends to be retrievable are present in the fetched content, not only in an image or unrendered script |
| Links | Internal links relevant to navigation and topical context resolve correctly in the fetched content |
| Canonicals | Canonical tags resolve to the correct, intended authoritative URL |
| Headers | Relevant HTTP response headers (including X-Robots-Tag, caching headers) reflect the intended policy |
| Schema | Structured data in the fetched content is present, valid, and matches the shared metadata and schema standard for this pillar |
| Performance | Page load and response time fall within a reasonable range that does not risk timeout-based failures for automated fetches |
| Logs | Server logs show successful, verified requests from the intended crawler, not only from spoofed or unverified User-Agent strings |
Policy Decisions And Rollback
Deciding which crawlers to allow, and for which purpose, is a business and security decision, not a default technical setting. Build an AI Access Control Matrix recording, for each provider and token: the disclosed purpose, current robots and infrastructure behavior, the IP-verification source used to confirm identity, the organization’s desired policy, an accountable owner, the validation test used to confirm the policy is actually in effect, the date it was last checked, and a stated risk level for getting the decision wrong in either direction.
| Field | Purpose |
|---|---|
| Provider and agent/token | Identifies exactly which crawler or token this row governs |
| Disclosed purpose | What the provider states this crawler is used for, per current documentation |
| Robots behavior | Current robots.txt, meta, and header treatment for this agent |
| IP-verification source | The provider-published method used to confirm requests genuinely come from this crawler |
| Desired policy | Allow, block, or conditionally allow, and under what conditions |
| Owner | Who is accountable for this policy decision and its implementation |
| Validation test | How the policy's actual effect is confirmed, referencing the acceptance test above |
| Last checked | The date this row was last reverified against live documentation and live behavior |
| Risk | The organization's assessed risk of the current policy, considered honestly in both directions |
Failure Modes
Frequently Asked Questions
Does blocking GPTBot also block OAI-SearchBot?
No. OpenAI documents these as separate tokens for separate purposes, training data collection versus search discovery. Blocking one does not, per current documentation, block the other; each requires its own deliberate policy decision.
Is robots.txt a security control?
robots.txt a security control?No. It is a convention that well-behaved, cooperative crawlers are expected to honor; it provides no enforcement against a client that ignores it. Genuine access control requires infrastructure-level measures such as WAF rules, verified through IP-based authentication, not robots directives alone.
Does Google-Extended control whether we appear in Google Search results?
Google-Extended control whether we appear in Google Search results?No, per Google's own documentation. It is a control token governing eligibility for certain AI-feature training and grounding uses of already-crawled content; it does not control Google Search inclusion itself.
How do we verify a crawler is genuinely who it claims to be?
Use the provider's own published verification method, typically reverse DNS confirming the requesting IP resolves to the provider's documented domain, cross-checked against published IP ranges where available. Never rely on the User-Agent string alone.
Who should own this policy inside our organization?
A combination of technical SEO or search strategy (setting the desired policy) and security or infrastructure ownership (implementing and monitoring it); this guide assumes both are involved, not one acting without the other.
Where should we start?
With the AI Access Control Matrix, populated with your current, actual robots and infrastructure configuration, verified against the acceptance test, not assumed from configuration intent.